Data · Websites and AI crawlers
US law-firm websites and AI crawlers
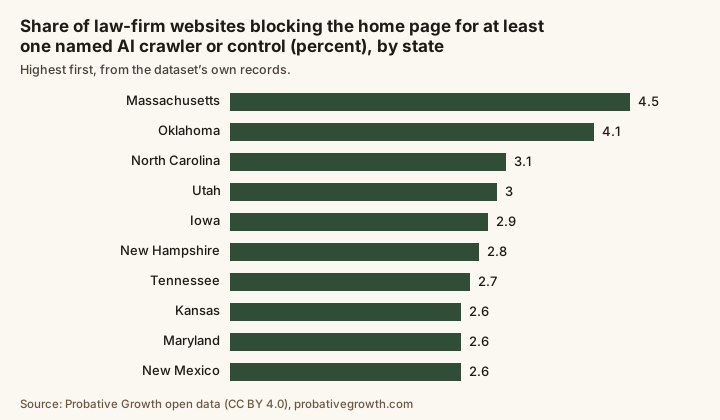
Of 44,118 US law-firm websites with a crawler file answer read, 2.2% block the home page for at least one of eight named AI crawlers and controls, and 8.0% name GPTBot in the file at all. (source: Probative, law-firm-ai-readiness dataset, national row) 0.1% of 44,118 home pages show under 200 characters of text before JavaScript runs, and 7.6% of 42,840 websites have Spanish pages that name no translation service. By state and market, read 2026-11-03 to 2026-11-04; the other host name of each website was asked 2026-11-06.

What is in this dataset?
What US law-firm websites show AI crawlers, measured from the public files and pages of the websites themselves: which of eight named AI crawlers and controls (GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, Claude-User, PerplexityBot, Google-Extended, meta-webindexer) each site's crawler file (the plain-text file at its root that tells crawlers what they may visit) names and whose access to the home page it blocks, whether the apex and www host names lead to one site, how much home-page text a reader gets before JavaScript runs, and how their Spanish pages present themselves. It also counts FAQPage and Organization structured data and nosnippet and max-snippet tags on the same pages. Aggregates by state and market only; no firm or website is named or scored.
Use it to set your own site against the law firms in your state or market before you pay for AI search work: whether your crawler file treats these crawlers the way you intend, whether your home page has text before JavaScript runs, and how common a Spanish page is where you compete. A share is the percent of the base named on the row.
- Records
- 77
- Look up by
- 45
- state
- Primary-source records
- 77
The letters are explained in what P, S, D and U mean.
Where does the data come from?
The pages are read by our census crawler (a descriptive user agent of its own, a spaced rate, a few pages per website, no JavaScript). Each site's crawler file is matched for each listed crawler's name by the internet standard for those files (the group naming the crawler, else the group for all crawlers; the longest matching path wins, an allow wins a tie). The raw HTML of the pages read gives the visible text before JavaScript, structured data types, search meta tags and Spanish class. One further request to the other host name (www or apex) of each website records its answer, with no redirect followed. Websites count when their home page title or legal structured data shows a law firm and they list a US office. Every share is recomputed separately from the site-level rows, and 20 random websites are re-derived from their raw pages.
- Period covered
- November 3, 2026 to November 4, 2026
- Places
- The whole US, states and metro areas
- How often we refresh it
- Every quarter
- The source's next release
- February 2027
- Records read
- November 6, 2026
The sources the records cite most
How to read these sources
- Other websites (1 of 1 listed). Any other site is read for what it shows on the page, and its quality is weighed before use: who wrote it, what it cites, and whether it states a date. We prefer the primary source behind it when one exists.
What does a record look like?
-
United States: of 44,118 US law-firm websites with a crawler file answer read, 2.2% block the home page for at least one of eight named AI crawlers and controls (GPTBot 2.1%, OAI-SearchBot 0.0%, ClaudeBot 2.0%, PerplexityBot 0.1%, Google-Extended 2.0%); of 44,118 websites, 0.1% show under 200 characters of text before JavaScript runs, 15.6% carry FAQPage markup and 68.2% Organization-family markup; of 42,840 websites, 7.6% have Spanish pages that name no translation service, 0.8% Spanish pages that name one, 3.9% only a translation widget and 87.7% no Spanish pages.
Status P · checked November 6, 2026 · source: Probative, law-firm websites read 2026-11-03 to 2026-11-04 (method and data)
-
California: of 7,258 US law-firm websites with a crawler file answer read, 2.2% block the home page for at least one of eight named AI crawlers and controls (GPTBot 2.1%, OAI-SearchBot 0.0%, ClaudeBot 2.1%, PerplexityBot 0.0%, Google-Extended 2.1%); of 7,258 websites, 0.2% show under 200 characters of text before JavaScript runs, 16.3% carry FAQPage markup and 64.4% Organization-family markup; of 7,012 websites, 10.1% have Spanish pages that name no translation service, 1.2% Spanish pages that name one, 5.3% only a translation widget and 83.4% no Spanish pages.
Status P · checked November 6, 2026 · source: Probative, law-firm websites read 2026-11-03 to 2026-11-04 (method and data)
-
Texas: of 4,270 US law-firm websites with a crawler file answer read, 2.5% block the home page for at least one of eight named AI crawlers and controls (GPTBot 2.3%, OAI-SearchBot 0.1%, ClaudeBot 1.9%, PerplexityBot 0.1%, Google-Extended 2.3%); of 4,270 websites, 0.2% show under 200 characters of text before JavaScript runs, 16.7% carry FAQPage markup and 68.9% Organization-family markup; of 4,116 websites, 11.2% have Spanish pages that name no translation service, 1.5% Spanish pages that name one, 5.3% only a translation widget and 82.1% no Spanish pages.
Status P · checked November 6, 2026 · source: Probative, law-firm websites read 2026-11-03 to 2026-11-04 (method and data)
The full records add the dates, the quoted source text and every field in the CSV and JSON files below.
What each of the 44 main columns means
jurisdiction- Two-letter state code, or US; a market row carries its state's code
level- us, state or metro (a market on this site, by its core counties)
areaName- The place the row covers
market- The market's page on this site (market rows)
value- The headline share: % of websites blocking the home page for at least one of the eight AI crawlers and controls
unit- What value measures
websites- US law-firm websites read in the group (N); every state and market has at least 100
robots_read- Websites whose crawler file answer was read: the base of the crawler-file shares
share_robots_file- % of those with a crawler file holding text
share_block_any- % blocking the home page for at least one of the eight crawlers
share_block_gptbot- % whose crawler file blocks the home page for GPTBot (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_oai_searchbot- % whose crawler file blocks the home page for OAI-SearchBot (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_chatgpt_user- % whose crawler file blocks the home page for ChatGPT-User (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_claudebot- % whose crawler file blocks the home page for ClaudeBot (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_claude_user- % whose crawler file blocks the home page for Claude-User (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_perplexitybot- % whose crawler file blocks the home page for PerplexityBot (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_google_extended- % whose crawler file blocks the home page for Google-Extended (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_block_meta_webindexer- % whose crawler file blocks the home page for meta-webindexer (its own group, else the group for all crawlers; longest match wins, an allow wins a tie)
share_named_gptbot- % whose crawler file names GPTBot in a User-agent line
share_named_oai_searchbot- % whose crawler file names OAI-SearchBot in a User-agent line
share_named_chatgpt_user- % whose crawler file names ChatGPT-User in a User-agent line
share_named_claudebot- % whose crawler file names ClaudeBot in a User-agent line
share_named_claude_user- % whose crawler file names Claude-User in a User-agent line
share_named_perplexitybot- % whose crawler file names PerplexityBot in a User-agent line
share_named_google_extended- % whose crawler file names Google-Extended in a User-agent line
share_named_meta_webindexer- % whose crawler file names meta-webindexer in a User-agent line
apex_read- Websites with an apex and a www host name asked: the base of the host shares
share_apex_same- % where the other host name redirects to the site's host
share_apex_split- % where the other host name answers its own page (200, no redirect)
share_apex_other- % where the other host name gives any other answer (an error status, or a redirect elsewhere)
share_apex_none- % where the other host name gives no answer (no DNS, no connection or a certificate that fails)
share_static_under_200- % of websites whose home page shows under 200 characters of visible text in the raw HTML, before JavaScript runs
median_static_chars- Median characters of visible text on the home page before JavaScript runs
share_faq_schema- % with FAQPage structured data on the pages read
share_org_schema- % with Organization, LocalBusiness, LegalService, Attorney or a close type on the pages read
share_snippet_limit- % with a search meta tag saying nosnippet or max-snippet of 0 or more on the pages read
share_snippet_unlimited- % with max-snippet:-1 (no limit) on the pages read
spanish_read- Websites whose Spanish status could be classed from the pages read: the base of the Spanish shares
share_spanish_own- % with a page read in Spanish whose HTML names no translation service
share_spanish_machine- % with a page read in Spanish whose HTML names a translation service
share_spanish_widget- % with a translation widget on the home page and no Spanish page
share_spanish_none- % with no Spanish page, link or translation widget
static_threshold_chars- The threshold, in characters of visible text, behind share_static_under_200
period- First and last read date
How do I use it in my own tools?
ai_readiness_lookup- For one two-letter state code (or US): the shares of law-firm websites by crawler-file rule for each AI crawler, text before JavaScript, FAQPage and Organization markup and Spanish class, with the state's market rows.
ai_readiness_compare- The same figures for several states side by side.
ai_readiness_search- Rows whose text matches the words given, such as a state, a market or a crawler.
How to cite this dataset
You can reuse, adapt and republish this data, including commercially, under the Creative Commons Attribution 4.0 license (CC BY 4.0). The only condition is that you credit Probative and link to the source.
- Version
- 1.0.0, released November 6, 2026
- Every version
- 10.5281/zenodo.24015037 (always points to the newest)
- License
- CC BY 4.0
Download the data
- CSV: law-firm-ai-readiness.csv 82 KB · one row per record (columns in README.txt)
- JSON: law-firm-ai-readiness.json 189 KB · every record with its sources
- CSV: law-firm-ai-readiness-values.csv 3 KB · one row per value of the columns some records have (id, column, value)
Free, no email or login. The files are hosted on this site and Zenodo, a public research archive.
Suggested citation
Probative. (2026). US law-firm websites and AI crawlers: crawler-file rules, text before JavaScript, snippet limits and Spanish pages, by state and market (Version 1.0.0) [Data set]. Zenodo. https://doi.org/10.5281/zenodo.24015038
Credit line for a chart, table or article
Source: Probative, US law-firm websites and AI crawlers: crawler-file rules, text before JavaScript, snippet limits and Spanish pages, by state and market, version 1.0.0, https://doi.org/10.5281/zenodo.24015038, licensed CC BY 4.0.
Bluebook-style citation, for US legal writing
Probative Growth, US law-firm websites and AI crawlers: crawler-file rules, text before JavaScript, snippet limits and Spanish pages, by state and market, Version 1.0.0 (Nov. 6, 2026), https://doi.org/10.5281/zenodo.24015038.
Add to a reference manager (Zotero, Mendeley, EndNote)

Not legal advice. These are counts of what law-firm websites' crawler files and raw pages said when read. A rule in such a file is what the file says; it does not show what any AI tool does, and nothing here measures whether a firm appears in AI answers. The counts describe no firm's quality.
What changed recently?
- 2026-11-06 · Crawler-file rules for eight named AI crawlers and controls, the home-page text a reader gets before JavaScript runs, FAQPage and Organization markup, snippet limits, apex and www hosts and Spanish pages on 44,118 US law-firm websites: 2.2% block the home page for at least one named AI crawler or control. (source)
The full log is in changes.json.
What are the limits?
- A rule in a crawler file (the plain-text file at a site's root that tells crawlers what they may visit) is what the file says: it does not show how any AI tool behaves, and nothing here measures whether a firm appears in AI answers.
- A website counts when its home page title or legal structured data shows a law firm, so a page that names no law firm in its raw HTML is outside the group; the share under 200 characters is therefore a floor.
- The test is automatic: a review of the home page titles of 150 random websites from the group found 5 that were not law firms (for example a directory, a city attorney's office or a lawyers' association).
- A Spanish page that names no translation service can still have been translated by a tool: the class says how the page presents itself, not who wrote it or how good it is.
- The group is 44,118 of the census's 96,885 US firm websites: those with saved pages that also pass the home-page test, not a drawn sample. Against the full list, the group shows a Spanish signal on 11.7% against 9.5%, an llms.txt file on 35.0% against 31.6% and legal markup on 36.8% against 27.8%, and legal markup is one way into the group, so these shares, the markup shares most of all, likely run above the full list. Every state and market row rests on at least 100 websites.
- Records older than 130 days since their last check are marked
stalein the files until we re-check them. Every confirmed error we fix is listed in the data corrections log.
Found a wrong value? Report an error with the record id and the source that shows the right value.
Check a value yourself
- Claim. Copy the figure and the record id it comes from; every record in the files has an id.
- Source. Open the source link on that record and find the same row, rule or table.
- Compare. Match the value, the unit and the date the record was read. A newer source edition can differ without our record being wrong.
- Report or cite. If they differ, report the error with the record id and the source. If they match, cite the record with its read date.
Two numbers for what looks like the same thing? Check that they measure the same thing before you decide one is wrong: the same place, the same period, the same unit and the same definition. The column notes on this page say what each of ours counts.
Running a firm? You don’t need the raw data: we handle your state’s ad rules for you. See where your firm stands first.
Cite this data as: Probative Growth, US law-firm websites and AI crawlers: crawler-file rules, text before JavaScript, snippet limits and Spanish pages, by state and market, 2026, https://doi.org/10.5281/zenodo.24015038. More formats in the citation kit.
Published by Probative Growth, a marketing agency for law firms. See our services and pricing.
Free
Get your free review.
Send us your firm’s website. Probative Growth records a 90-second video of what clients see when they look you up, and emails it with a one-page summary within 2 business days. No logins, no call needed.
Not sure where to start? Answer 7 questions Ready to talk? Talk to us Or see what AI says about your firm
Your free review: It covers your Google listing, website, phone and ads, from public information.